Oscar Puming Jiang
PhD student
National University of Singapore
Research Interests
If you're an undergrad interested in robotics research, talk to as many people in the field as you can, including me! I don't have the bandwidth to take on new students right now, but I'd love to help however I can. Feel free to email me to arrange a chat.
About
I am a PhD student at the School of Computing, National University of Singapore, advised by Prof. Harold Soh.
Before joining NUS, I completed a B.A. in Engineering and an M.Eng. at the University of Cambridge, followed by an M.Res. at Imperial College London, where I was supervised by Dr. Nicole Salomons. I received First Class Honours / Distinction across my previous degrees.
Research
My research focuses on the reliable reuse of learned robot skills. Every learned skill works only within some boundary of conditions. I study how to expand that boundary and how to know where it lies, so a robot can tell when a skill can be trusted.
Expanding the Skill Boundary
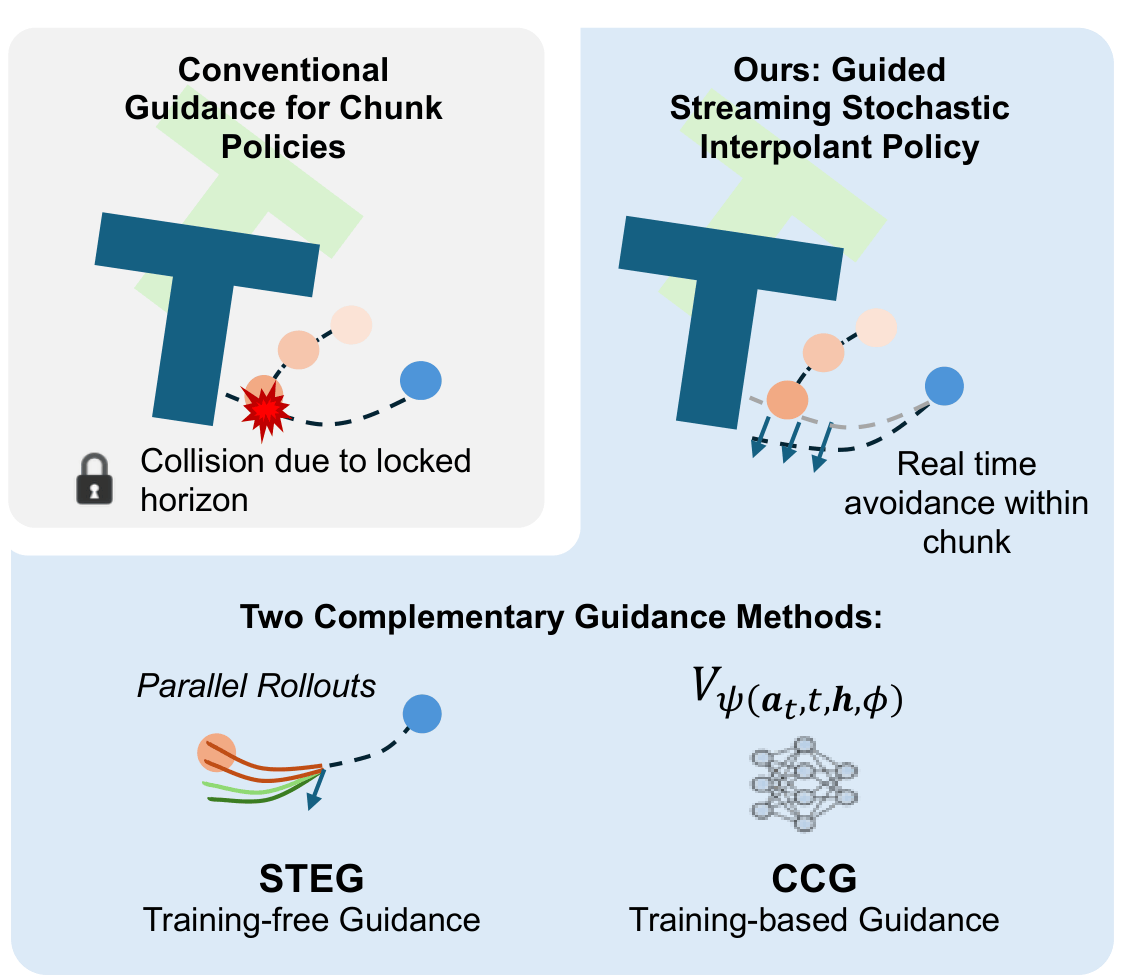
A policy is trained once, but new objectives and constraints keep arriving. How can we widen where it works, both by shaping what it learns and by steering it at deployment?
Understanding the Skill Boundary
A skill's name says little about where it succeeds. How can we predict where a learned policy works, and state it in a form that planners and agents can use to invoke and compose it correctly?
Selected Publications
View All →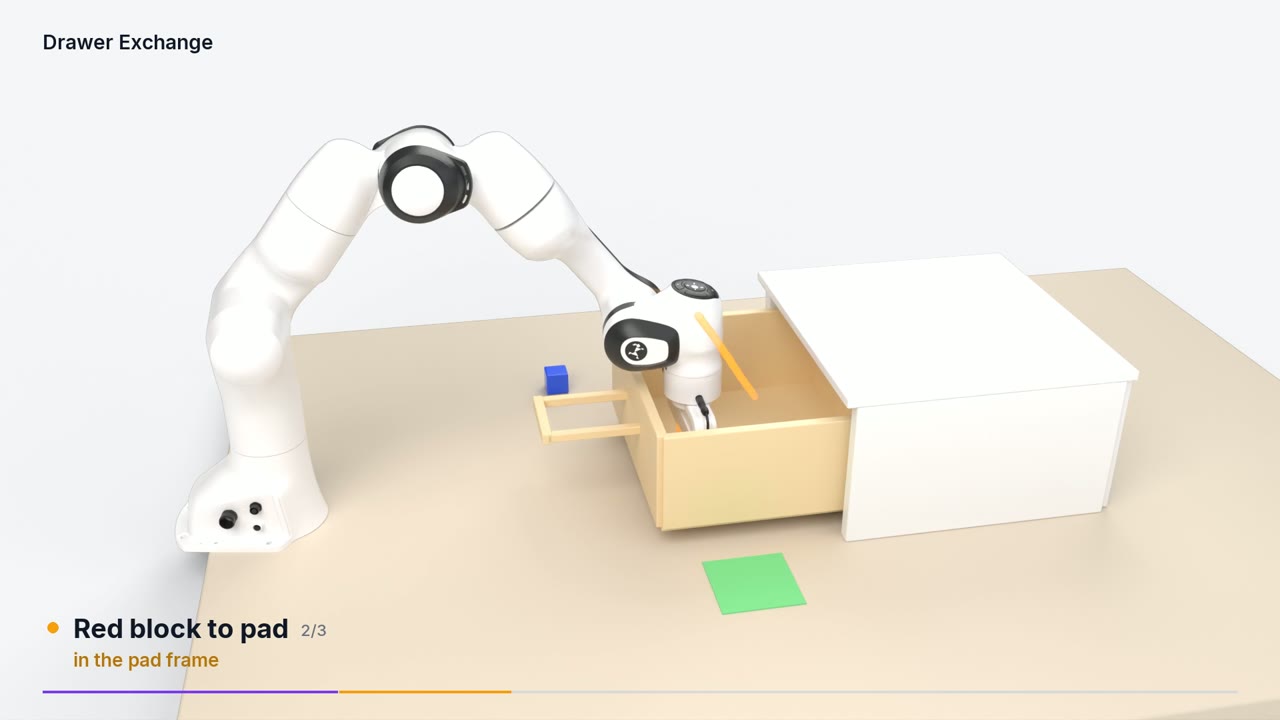
News
Our work GSSIP has been accepted to R:SS 2026. I will present the work orally in Sydney! 🎉
Starting my PhD at the National University of Singapore